3
High
Homepage
No social proof
The hero lacks any trust signals like review count or rating, so first-time visitors may doubt comfort claims.
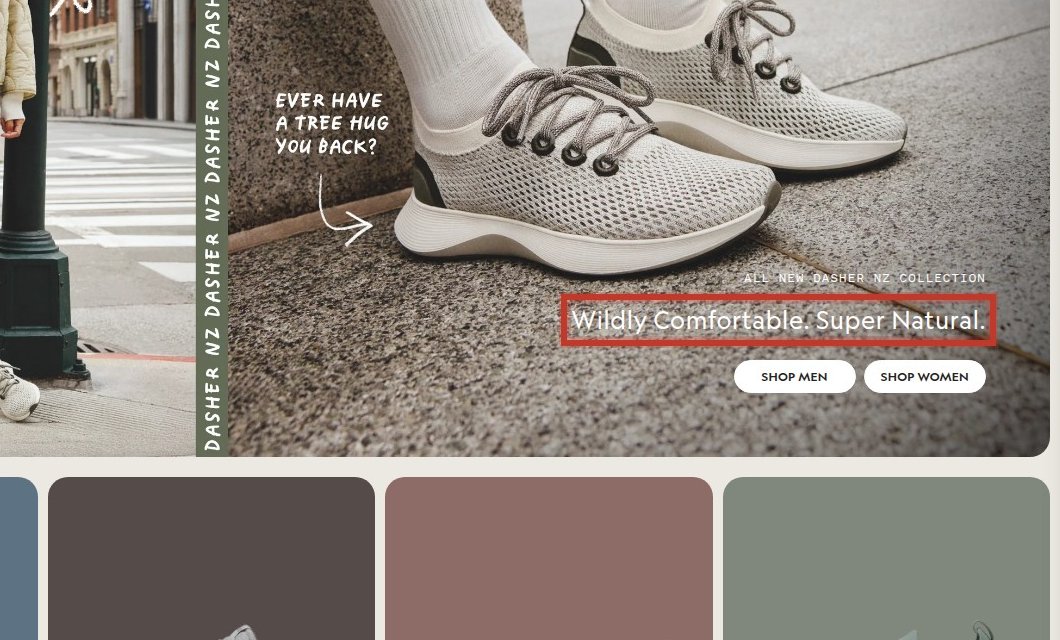
⚠ No social proofThe hero section's main heading lacks trust signals like review counts or ratings, potentially causing first-time …
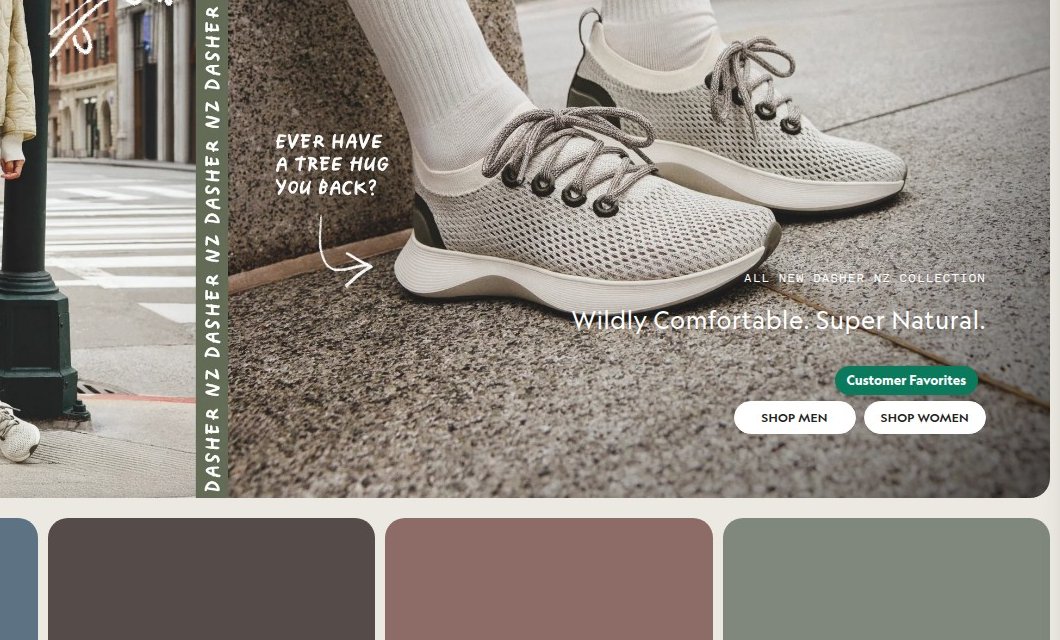
Both are photographs of the live page — the right side has the
change applied in the browser.
Evidence
Observed on the live site
✓ Flagged independently by 1 of 7 analysts
- Hero H1: 'Wildly Comfortable. Super Natural.' with CTAs 'SHOP MEN' and 'SHOP WOMEN' but no review stars or count visible.
Business case
If this change wins
$35,381 – $176,904
annual opportunity if it wins
Medium
Effort — 2-5 days
not testable at current traffic
A/B test duration
Prioritisation
PXL score: 5 / 10
| Question | Answer | Points |
|---|---|---|
| Is the change above the fold? | Yes | 1 |
| Is the change noticeable in under 5 seconds? | Yes | 2 |
| Does it add or remove an element? | Yes | 1 |
| Does it run on a high-traffic page? | Yes | 1 |
| Discovered via user testing? | No | 0 |
| Discovered via qualitative feedback (survey, support)? | No | 0 |
| Supported by heatmaps or session recordings? | No | 0 |
| Found via digital analytics or real-user field data? | No | 0 |
| Verified by direct technical measurement? | No | 0 |
Implementation
Hand this to your developer
- Surface
- Homepage — HOMEPAGE HERO
- Problem
- The hero lacks any trust signals like review count or rating, so first-time visitors may doubt comfort claims.
- Current state
- h1: Wildly Comfortable. Super Natural.; cta: SHOP MEN / SHOP WOMEN; notes: No social proof in hero section.
- Change
- h1: Wildly Comfortable. Super Natural.; cta: SHOP MEN / SHOP WOMEN; notes: Add a line under hero: 'Rated 4.7/5 by 50,000+ customers' or a small review widget.
- Acceptance criteria
- GIVEN a first-time visitor on the affected page
WHEN the change is live
THEN Add a line under hero: 'Rated 4.7/5 by 50,000+ customers' or a small review widget, with no regression at 375px and 1280px widths. - Tracking
- event: cro_no_social_proof on interaction with the changed element; verify it fires in BOTH variants before opening traffic.
- Success metric
- conversion rate + bounce rate on the affected page
- QA checklist
- Chrome / Safari / Firefox · 375px + 1280px · keyboard reachable · screen-reader name present · no CLS introduced
- Effort
- Medium — 2-5 days
- Test plan
- 299,882 visitors per variant (95% significance, 80% power); not testable at current traffic.
- Rollback
- Feature-flag the change; revert the flag if the primary metric drops for 3 consecutive days.